
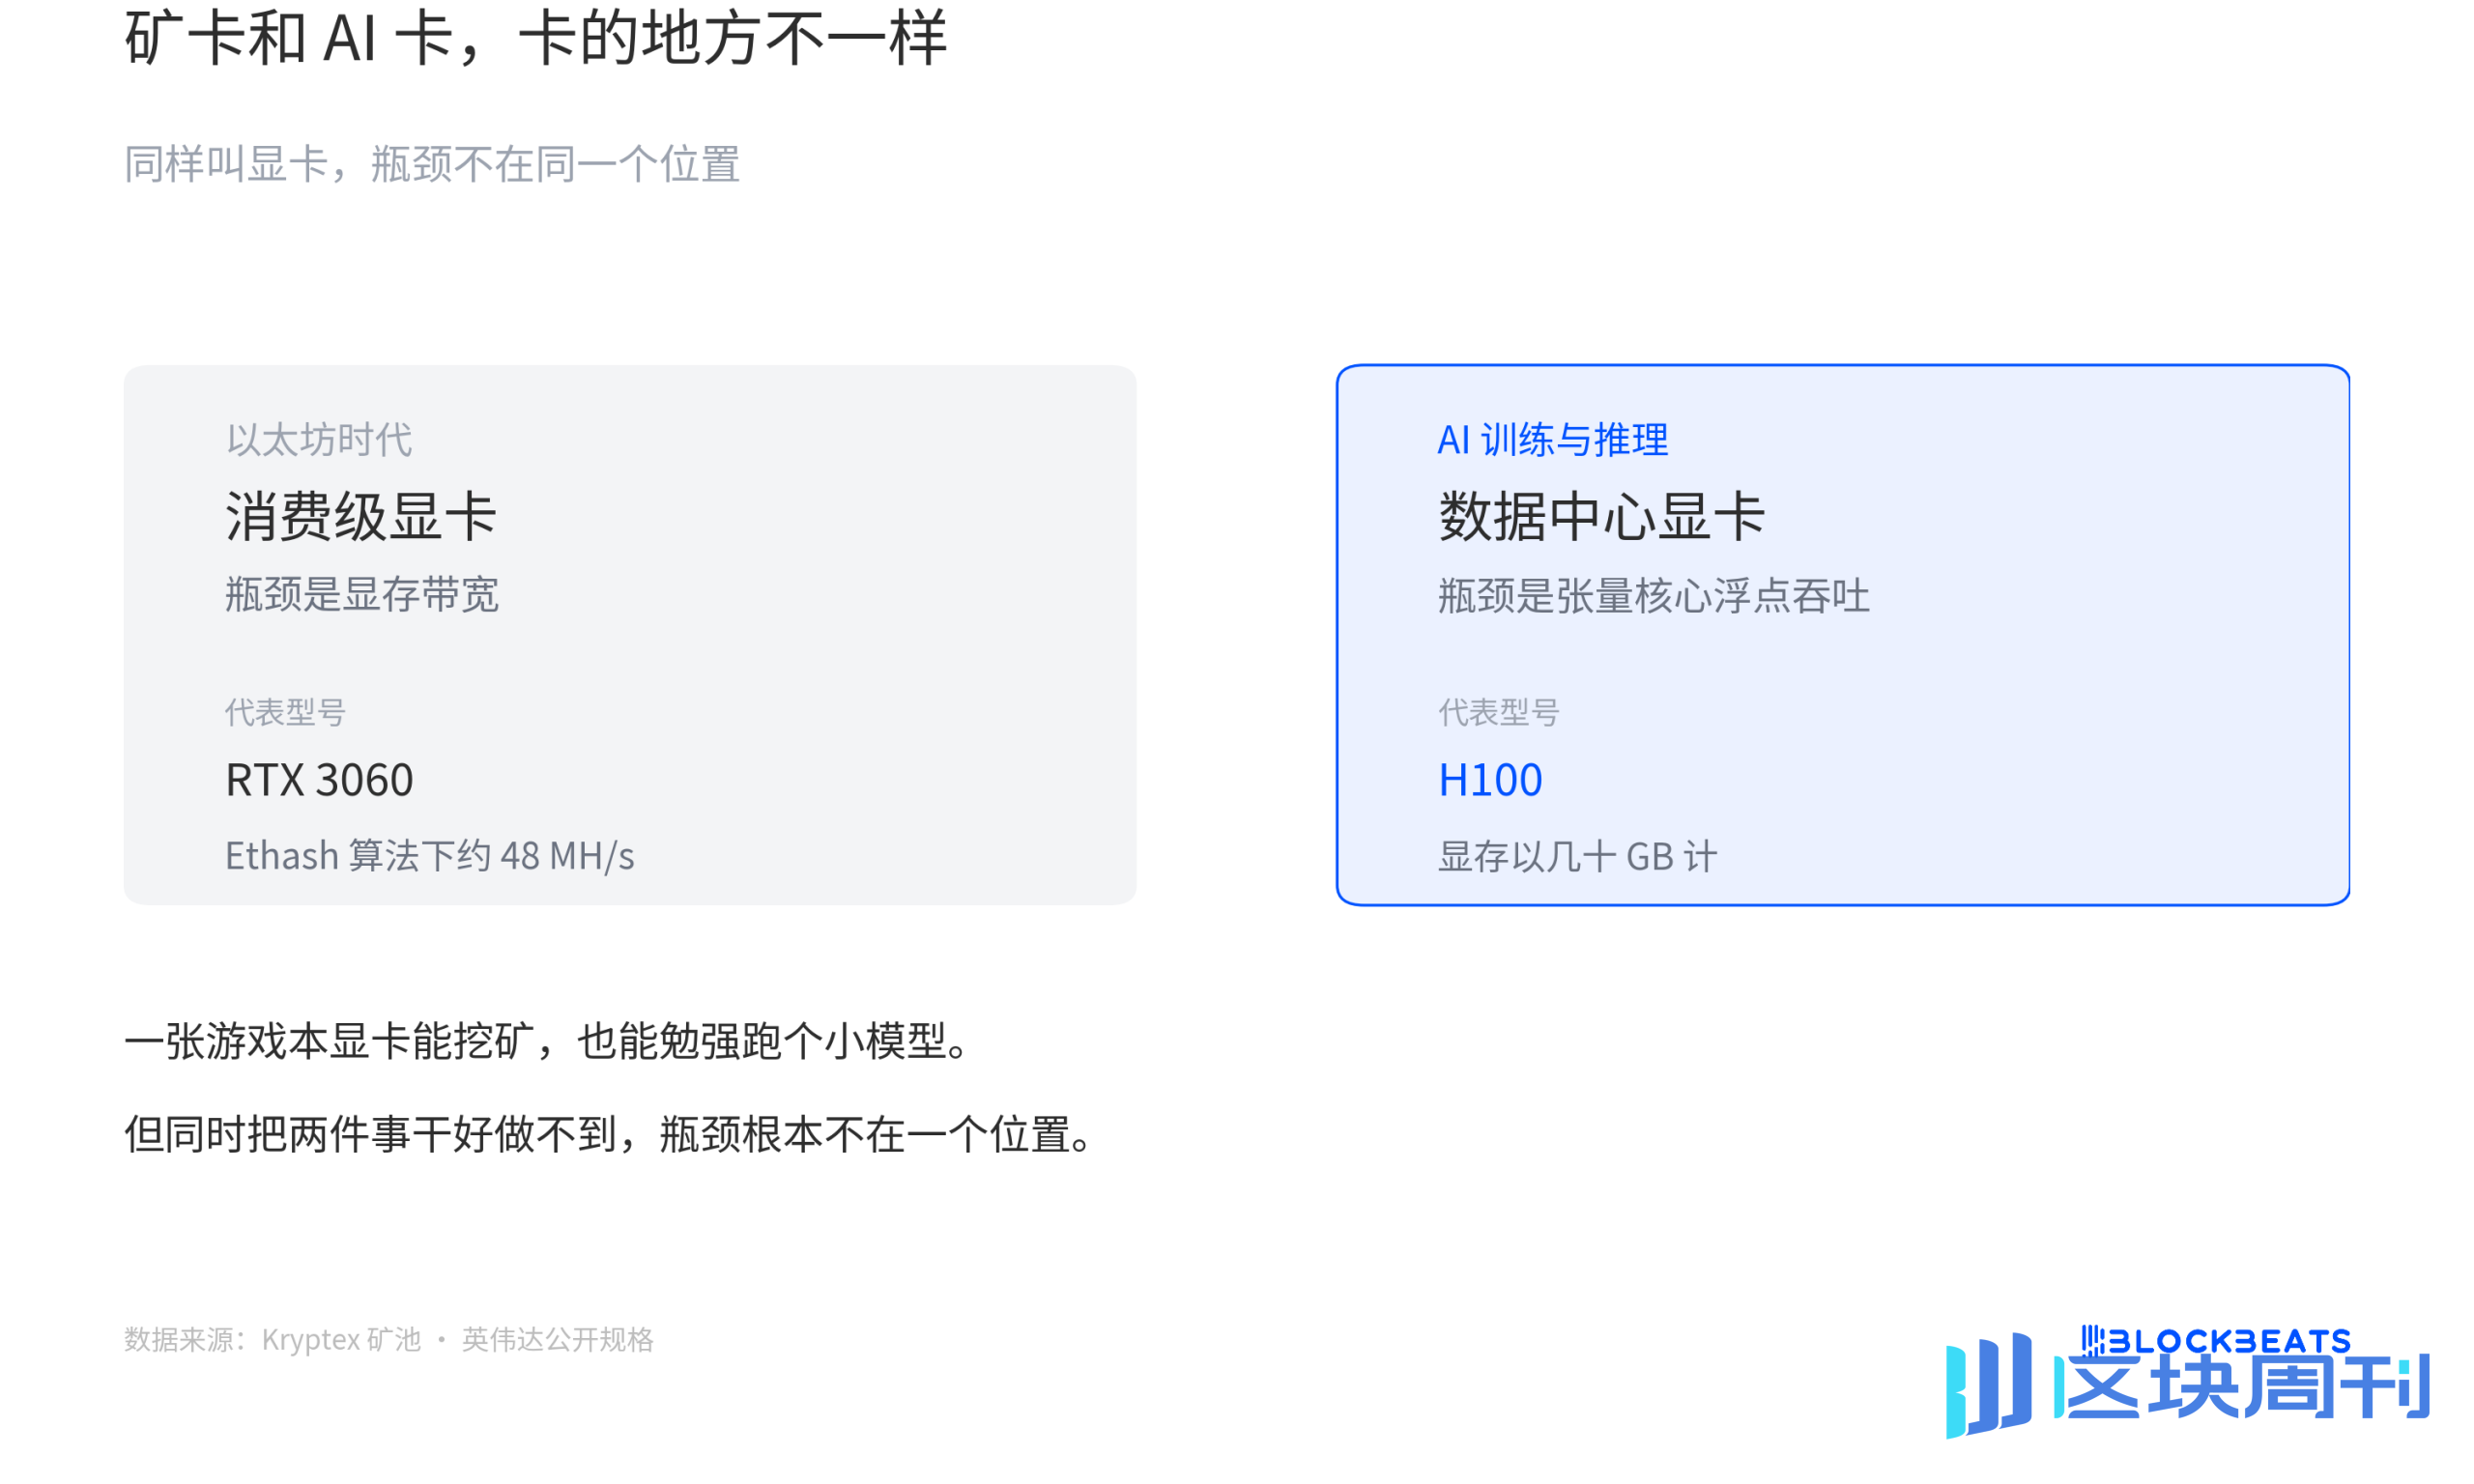
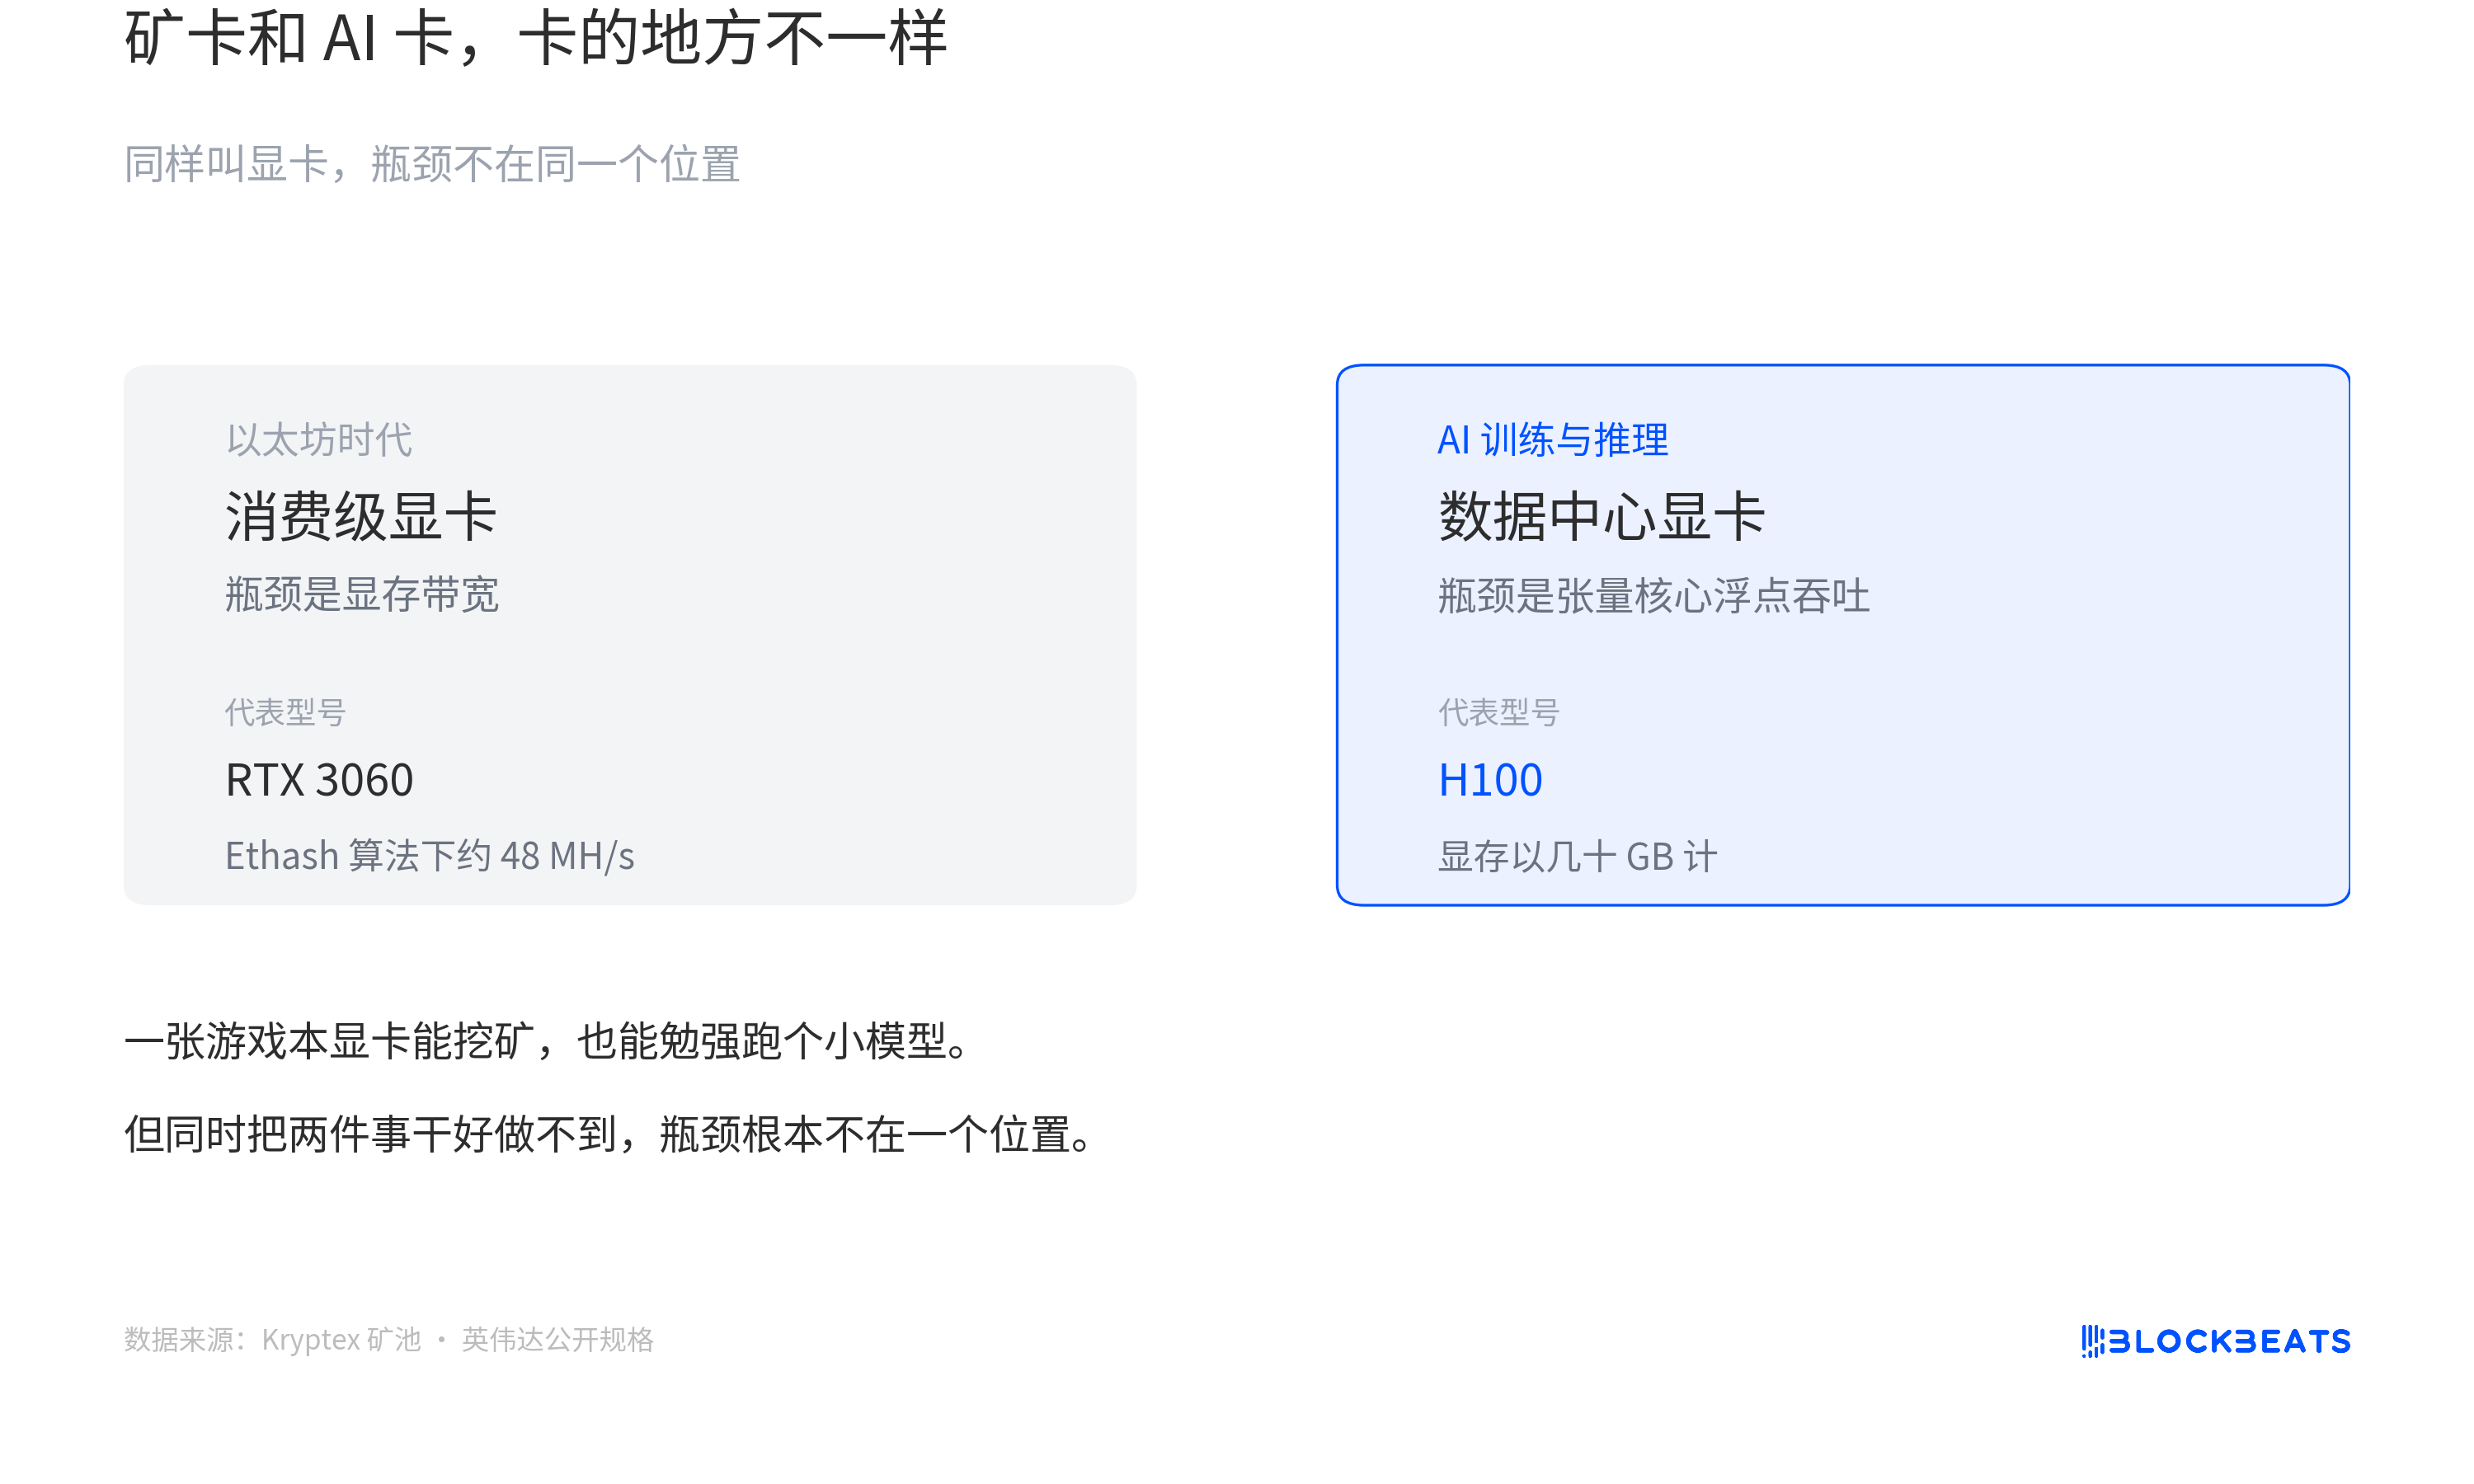
During the years when Ethereum was still POW, miners used consumer-grade graphics cards, and the algorithm was called Ethash. An RTX 3060 does about 48 MH/s on Ethash. At the time, some people did think that since both mining and AI rely on graphics cards, could the same card mine and run models at the same time.
This idea didn't work out because the two things are bottlenecked in different places. Ethash is memory-bandwidth-bound and computes fixed-difficulty hashes. AI needs tensor-core floating-point throughput and tens of GB of VRAM, with the main workhorses being data center cards like the H100. A graphics card in a gaming laptop can mine and can barely run a small model, but it can't do both well at the same time.
In 2019, Vitalik Buterin made a judgment on this matter. His original words were that if some kind of useful and easily verifiable computation could be found, cryptocurrency mining would become a huge wealth for society, but this is probably impossible.
Pearl claims it has done it. Vitalik's judgment from a few years ago is displayed prominently on Pearl's official website.
Pearl is an independent proof-of-work public chain, and its token is called PRL. Miners no longer repeatedly compute hashes; instead, they do matrix multiplication, which is the kind of multiply-add that every layer of a neural network performs. By design, the same GPU computation both produces blocks and issues coins, and also produces verifiable AI computation.
The official description of this is "energy, data, and money in one operation." Bitcoin binds energy and money together, AI binds energy and data together, and monetization binds data and money together. These three things used to meet two at a time; Pearl wants all three to happen simultaneously in one matrix multiplication.
The PoW line has been quiet for a long time. The last batch of new public chains that could make people sit down and seriously discuss them basically finished years ago. After that, the excitement has been in L2s, modularity, and restaking. A new PoW chain itself is rare. Now PRL, with a circulating market cap of 430 million USD, wants to tell what kind of story?
What problem does it want to solve
Bitcoin's proof of work has a characteristic: what miners compute has nothing to do with the real world. The same kilowatt-hour, if used to run models, can produce tokens, generate images, and do work. Many people feel it's a bit wasteful to use it for mining.
The real difficulty is not "usefulness," but permissionlessness. Permissionless means anyone can come mine, without registering, and no one reviews qualifications. Bitcoin's security model is built on this: no matter what you compute, the cost is the same. Once the work is replaced with something of real-world value, miners have an incentive to cut corners or choose a cheap input. So the question is not whether mining can be made useful, but whether it can be made useful while no one can cheat.
Pearl's own claim is that it replaces Bitcoin's random hashing with matrix multiplication, letting GPUs treat proof of work as a byproduct of AI workloads. The whitepaper directly uses the term "2-for-1." In plain terms, previously a batch of GPUs had only two destinations: either mine, burning electricity while issuing coins, or run models, burning electricity while producing tokens. Pearl wants to merge these two destinations into one.
Someone has calculated this idea in detail. Cryptography researcher Rafael Pass's paper "The Economics of Proof-of-Useful-Work" divides a machine's work into three types: pure mining, pure inference, and dual work that produces both simultaneously. Dual work is not free. The paper gives an example: a unit of computing power doing two things at once does not get two outputs, but about one and a half. If the overhead is small enough and the scale at which the token is accepted by the market is large enough, the block reward is equivalent to giving a rebate on the inference price, pulling in inference computing power that otherwise would not have been done. This reasoning is mathematically impeccable, but the trouble is that its three variables—overhead, token price, and inference demand—are not something Pearl can decide on its own. A footnote in the paper discloses that the author completed this work while consulting for Pearl Research Labs.
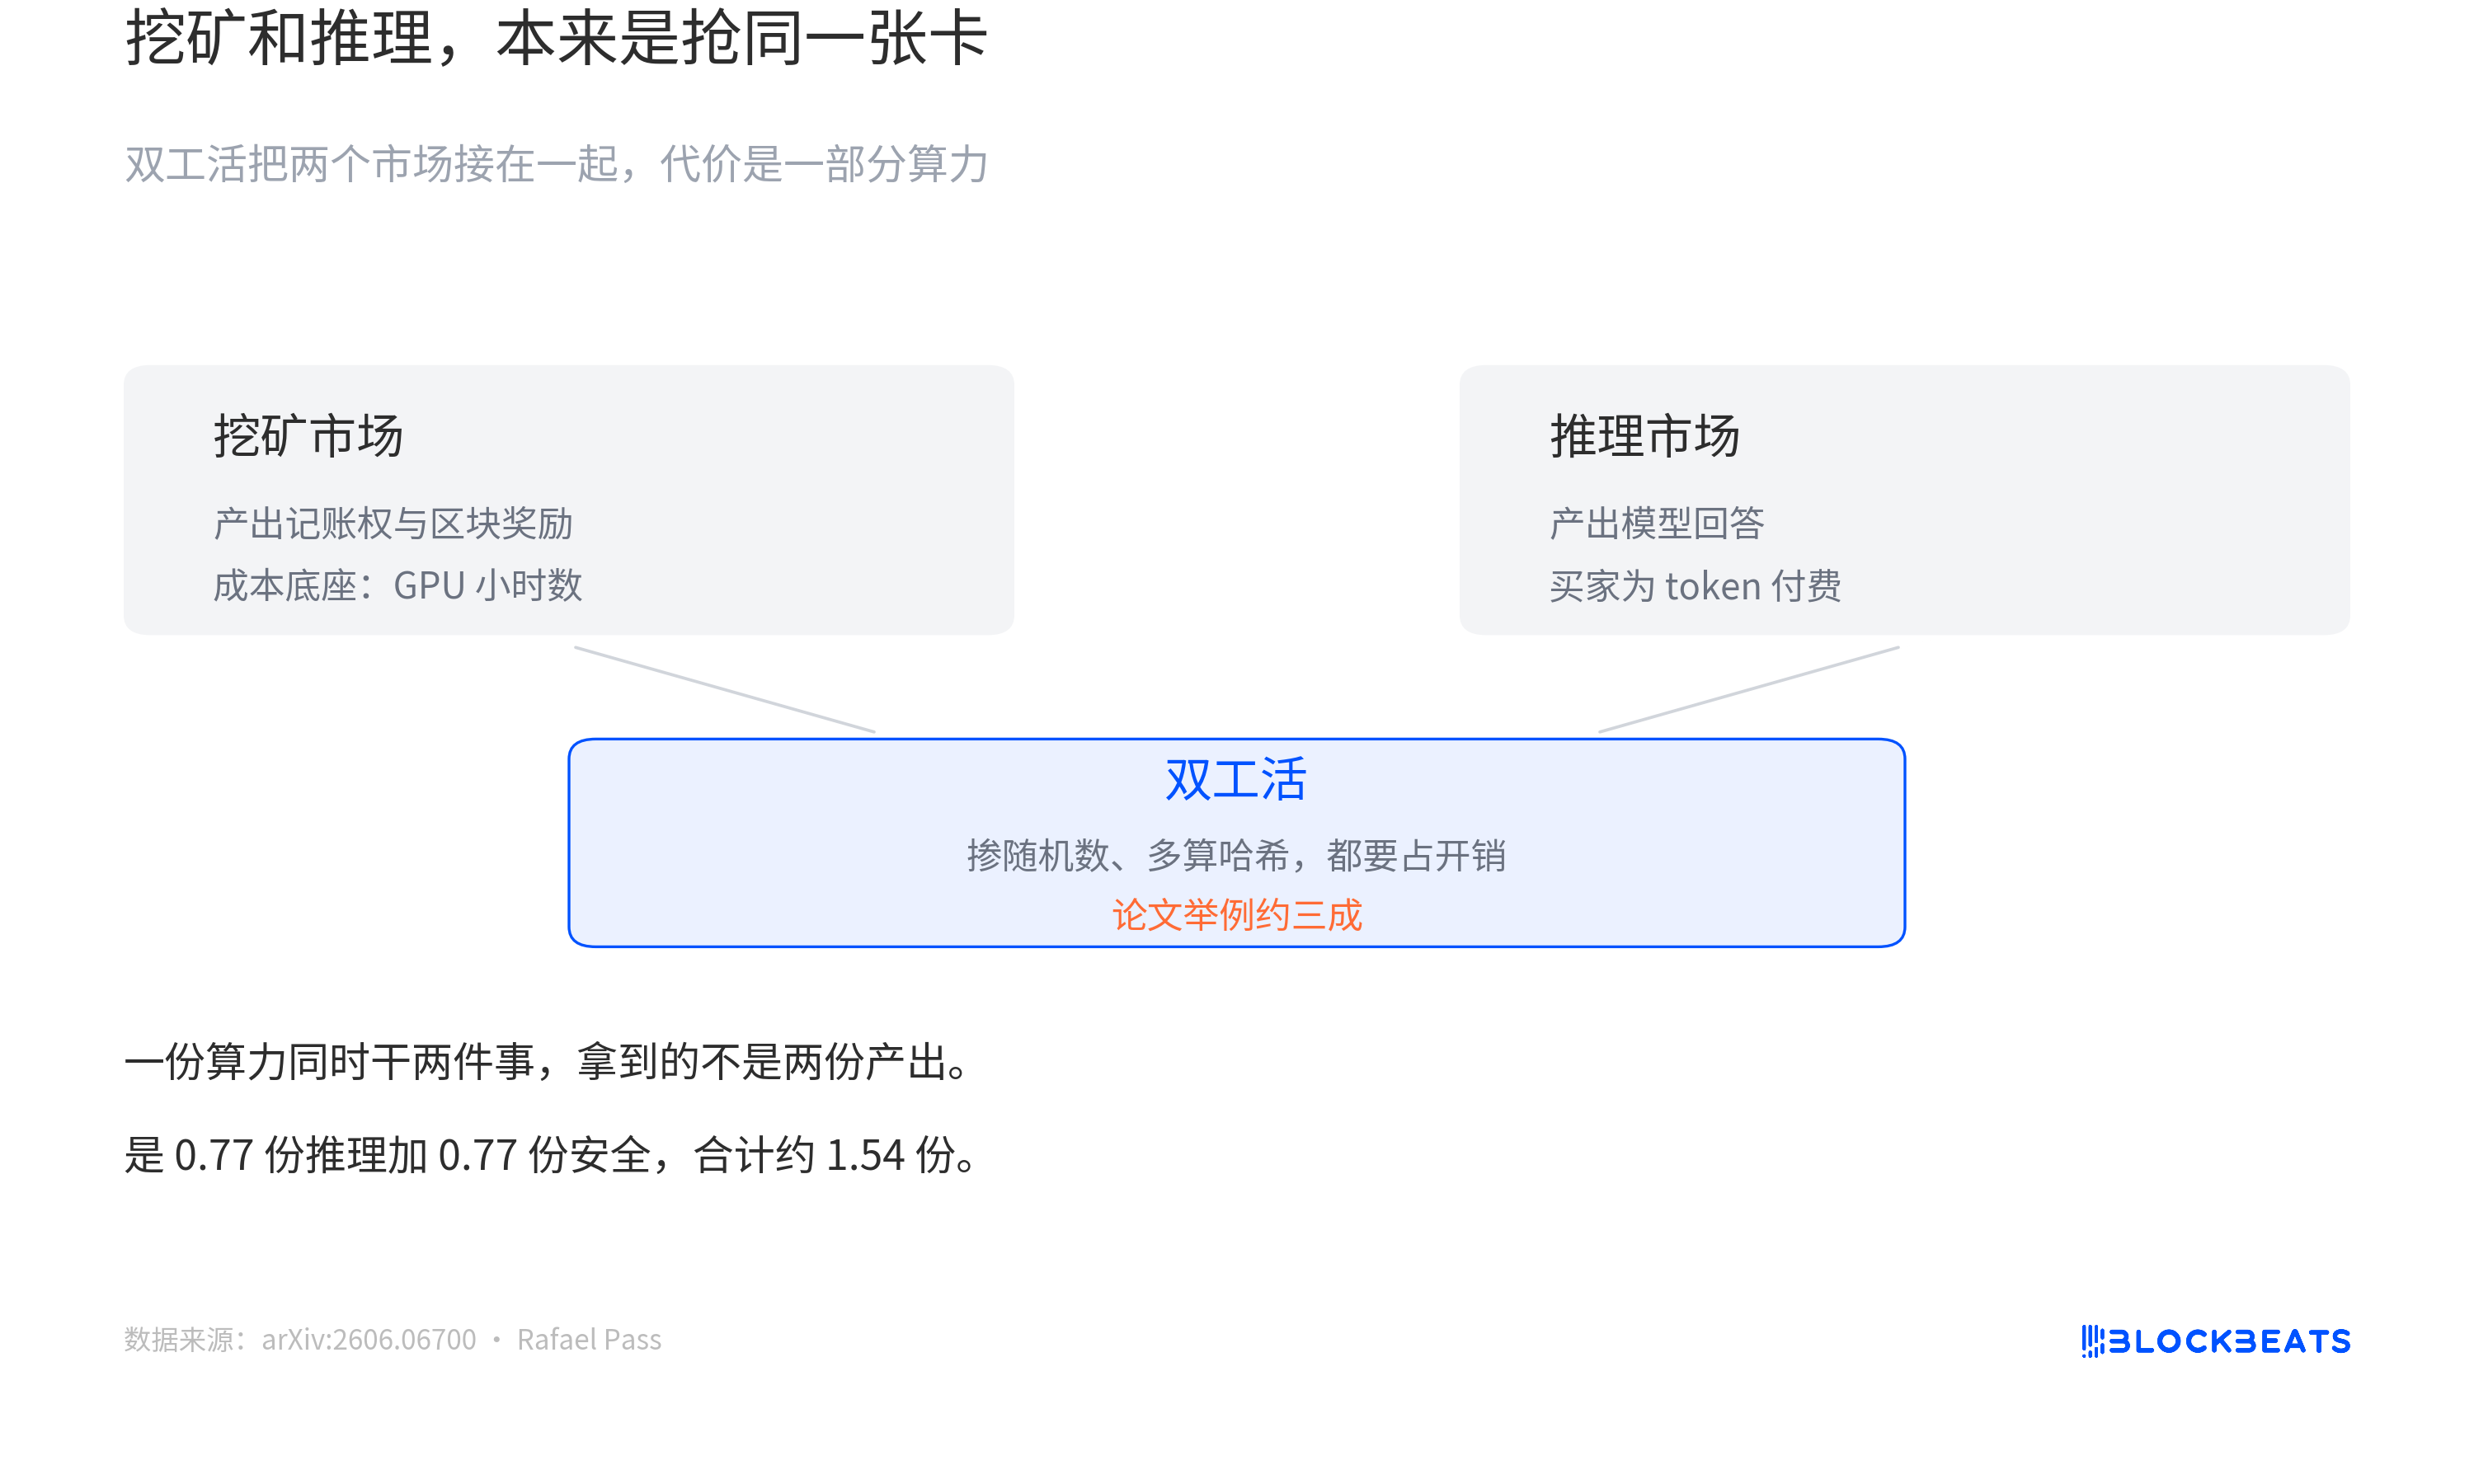
Pearl's operating logic
To explain how this system works, we first need to break down the term matrix multiplication. It was not invented by Pearl; it is a very old operation, and almost every layer in a neural network uses it.
A matrix is a table of numbers arranged by rows and columns. Two tables can be multiplied if the number of columns in the first equals the number of rows in the second. Each cell in the result table is the sum of the products of one row from the first table and one column from the second table, multiplied one-to-one and then all added together. Take the smallest example: the first row of A is 1 and 2, the first column of B is 5 and 7, then the top-left corner of the result table is 1 times 5 plus 2 times 7, which equals 19. The remaining cells are filled in one by one according to this rule.
In an AI model, one layer's computation can be written as "input times weights." A user's sentence is cut into vectors, multiplied by that layer's weight table to get a result, then passed through a nonlinear function and handed to the next layer. The larger the model, the larger the tables, and the number of multiply-adds in one pass can be in the trillions. GPUs are built for this kind of neat multiply-add, which is also why mining cards and AI cards are the same type of chip.
Ideally, things work like this. Someone asks a chatbot a question online, and the graphics card on the server starts running the model, doing matrix multiplication layer by layer. If this machine has Pearl's plugin installed and is running its certified open-source model, then these multiplications, while producing an answer, are also used to try their luck. After each small block is computed, a fingerprint is rubbed once. If the fingerprint is small enough, a lottery ticket is won, and winning gets the block reward. The user sees no difference, still gets the answer, and the price might even be a bit cheaper. The same batch of multiply-adds turns into tokens on one side and coins on the other.

For this system to work, it must first solve cheating. The miner has just two tables in hand, and he must first rub the tables into a fingerprint and submit it. So-called rubbing a fingerprint means taking all the numbers in this table and computing a hash together, compressing it into a very short segment. Only after the chain has seen this fingerprint will it tell him what random numbers to mix into the tables. The order is locked, and it's too late for him to change the tables. The official term for this action is adding noise. In plain terms, it means mixing a bunch of random numbers into the two tables. How much is mixed and where is determined by that fingerprint, and the miner cannot choose it himself.
Without mixing, there is a shortcut. Between clean A times B and the product after mixing in random numbers, there is only a difference of three correction terms. These three terms are not small in magnitude, but they are cheap to compute. The miner already has clean A and B in hand, so he could completely first compute the clean answer, then add these cheap correction terms to produce the answer with random numbers mixed in, without doing that big multiplication at all. It's like an exam question asking for 3987 times 2913, but the student has already memorized the answer and puts together a few small numbers to make it look like he calculated seriously.
So the protocol does not require the miner to hand over the computed result, only the rows of input he used, plus a proof. The verifier takes this part, mixes in the same random numbers, recomputes only this small block, and checks whether the fingerprint is correct. Recomputing a small block is cheap and sufficient to confirm he did not cheat. If these tables involve company weights or user data, an additional layer of zero-knowledge proof can be added to prove that the computation was indeed done, without revealing which two tables were used.

What step has it reached now
Go to Hugging Face and look; under the pearl-ai organization there are four certified models: Llama 3.3 70B, Llama 3.1 8B, Qwen3 30B, and Gemma 4 31B. Officially they are called "certified variants"; the approach is not retraining, but recompressing the same set of weights in Pearl's quantization format so they can perform inference while mining inside the plugin. The precision loss is very small; Gemma 4 31B's MMLU dropped from 90.93 to 90.56. As of October 9, 2026, the downloads of these four models in the past thirty days ranged from 195 to 6,424, and their likes were 0, 3, 5, and 6 respectively.
There is also a commercial outlet. In May 2026, Pearl partnered with Together AI to launch an interface running the Gemma model. According to Together's announcement, the call price is 25% cheaper than ordinary interfaces, with the difference offset by the future value of tokens.
The models are posted, the code is open-sourced, and then there is nothing more. In June 2026, researcher Abhinaba Basu's "The Usefulness Gap in Proof-of-Useful-Work" tested this. According to the network's computing power at the time of about 24 EH/s, equivalent to about 320,000 RTX 3090-level cards, estimated power consumption of 112 megawatts, and useful AI computing output was zero.
The author sampled 8,012 miner work units; all the hardware had inference capability, but in the main mining machine software, there were 4,803 strings related to matrix multiplication and 0 related to machine learning frameworks. He also wrote a mining program himself, filling tables with random numbers, and ran it successfully on Nvidia, AMD, CPU, and Apple chips, obtaining shares recognized by the mining pool, 44 in total. One person providing data and letting the model compute the result, and using the same card to mine coins, can be combined in design, but in actual operation they are separate.
So what is actually running on the network. According to the mining pool Kryptex's page, the network's computing power has risen to 46.37 EH/s, difficulty 2.26 TH, block time about 203 seconds, block reward 2,271.03 PRL, daily output about 966,000 coins, and coin price about $1.30. In six months, computing power has almost doubled, and the vast majority of this increase is still filling in random numbers. What is being done on the market now is mainly just this one thing: buy cards, plug them in, fill in random numbers, wait for settlement.
What problems are there
Let us imagine that the cafeteria posts a notice: whoever chops enough one hundred jin of vegetables can receive a wage. The act of chopping vegetables itself is real; knife skills, strength, and time all have to be spent. But the notice only checks whether you have chopped enough one hundred jin, not what vegetables you chopped. So someone brings a cart of rotten vegetable leaves, chops enough one hundred jin, and takes the wage. He did chop vegetables, and he really spent strength, it is just that the kitchen cannot use this pile of leaves.
Pearl is now stuck here. The protocol checks whether the fingerprint of the table matches, whether the result really equals the multiplication of two tables, whether the workload is enough for the difficulty; in the formal design there is also a statistical gate specifically to block inputs that can be seen at a glance to have been tampered with. It checks all of these. What it does not check is where these two tables came from. So miners can completely create two tables of random numbers themselves; the multiplication is just as hard, the fingerprint meets the standard just the same, and they can win just the same, except that no one wants to use the computed result. The protocol only recognizes the multiplication relationship, not semantics; "useful" here is a commercial issue, not a cryptographic guarantee.
This is not guesswork. According to the report mentioned earlier, all the machines sampled could run models, yet there was not a single line of inference code in the mining machine software, and the tables the author filled with random numbers himself also obtained shares recognized by the mining pool. At present, the network's computing power is around 45 EH/s, and the vast majority is still filling in random numbers.
The gap in scale can also be seen this way. The paper gave a counterfactual: if this design really operated as advertised, then at that time the 24 EH/s network should have produced about 7.7 million GPU hours of useful AI computing power per day. The paper also mentioned an indicator called the value destruction ratio; Pearl's measured value is 1.0, on par with Bitcoin, while Filecoin's is about 0.64.
Miners do not take inference orders, not because they do not understand, but because they have done the math. The paper estimates that coupling the inference engine with mining would lose about 10% to 30% of effective computing power. That is, taking real inference not only requires changing software and accommodating the rhythm of requests, but also first losing this portion of computing power. In years when the coin price is not high, this account is easily calculated as negative.
So how might this be solved. The paper listed several paths. One is to manage the source of the tables, requiring miners to use tables submitted by outside customers. The plugin and certified models that Pearl officially does now are moving in this direction: hand the model and plugin to miners; you use the real model to run inference, and that multiplication conveniently mines the coin as well. The difficulty is that it is voluntary; whether to take it is still up to miners to calculate their own economic account.
Another is to check whether the tables look like real ones. The weights of real models and casually filled random numbers differ in statistical characteristics. But the paper itself rejected this path: miners only need to adjust the distribution to fool the check, at almost zero cost. There are also several more distant paths that have not yet landed. Making the model source into a verifiable signature requires first having a public key system for the model side. Using trusted hardware to prove data provenance requires additionally trusting chip manufacturers and will also slow things down. Differentiating rewards, giving a bit more for using real data, requires first having a group of customers truly willing to pay.
Pearl's developer is Pearl Research Labs. Omri Weinstein is co-founder and CEO; this title comes from the Together AI partnership announcement. He is a researcher in complexity theory, holds a faculty position at Hebrew University, and is one of the authors of that foundational paper.
Another author, Ilan Komargodski, is also on the Hugging Face organization member list; whether his specific identity is employee or consultant cannot be proven from public sources. Another name that can be matched is Erez Badash, first author of the Hawkeye paper on GPU bitwise reproduction.
Bittensor has validators score the model outputs submitted by miners, with the score determined by a consensus called Yuma. io rents GPUs on demand for machine learning tasks. Pearl bets on a narrower assumption: the multiplication used for block generation itself can be wanted by someone.
It is betting that inference demand will grow large enough to consume block-generation computing power. At that point, miners themselves will calculate clearly that taking real orders is more cost-effective than filling in random numbers. If it cannot reach that point, then it is just a graphics card mining chain with changed mathematics; what is computed is homologous with AI, and unrelated to the expectations of any specific user.