
About 90% of Claude Code's own code has already been handed over to Claude to write.
With AI now writing the code, the number of changes has surged accordingly: from June to September, the number of PRs merged into the codebase more than doubled.
Across all of Anthropic, the changes merged into the main codebase each day rose from about 2,500 in May to over 30,000 in September.
With so much code, can humans still keep up with reading it? And if even the review is handed over to AI, who judges whether it has made a mistake?
On October 15, the Claude Code team publicly disclosed its internal code review process, revealing that while the number of PRs doubled, the proportion of PRs requiring rollback actually fell by more than 40% relative to that.
They achieved this through six layers of checks, plus a fallback mechanism for fast detection and fast rollback.
The Claude Code team's judgment is:
At this scale, line-by-line human review is no longer realistic.
But they did not abolish review; instead, they handed most of the work of reading code over to machines.
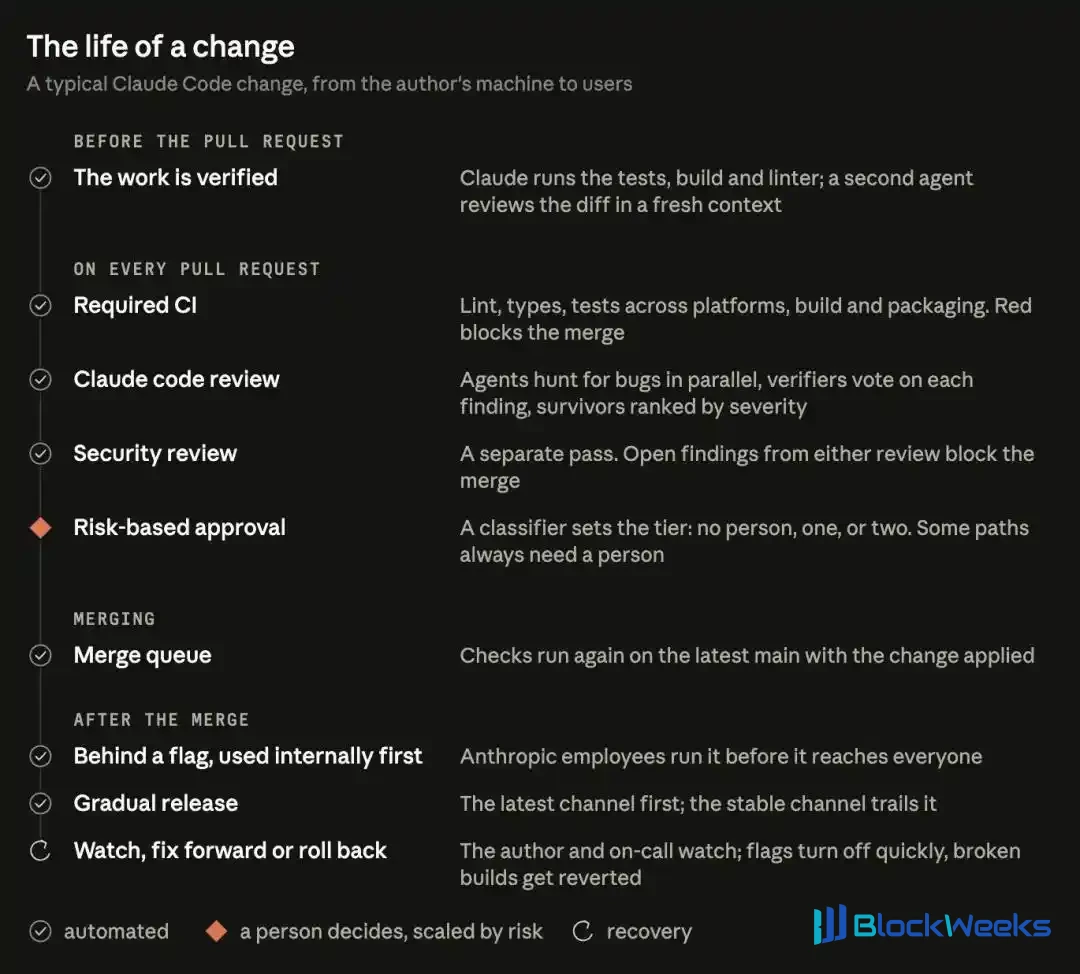
Before a piece of AI-written code goes live, it must first run tests, undergo AI and security review, and then, based on risk, a decision is made on whether human approval is needed.
In the view of the Claude Code team, "has anyone read this code" is not a precise enough question.
The real question should be:
What could go wrong with this change, and if it goes wrong, which check should stop it?
Before human review , AI first presents verification results
A single change must pass six checks, with a safety net at the end.
The first gate comes before creating a merge request (PR).
Claude must run tests and complete the build; for changes involving the interface, it must also take screenshots to compare against the design mockups.
Next, a sub-agent using a fresh context is dispatched to review the code diff; it did not participate in writing the code and is dedicated to finding faults.
The official requirement is very clear:
Claude must present the commands executed and their output; merely replying "all tests passed" does not count.
Ordinary developers can follow suit: when giving AI a task, clearly state how acceptance will be verified as well.
The second gate is the AI review on the PR.
Several agents search for bugs in parallel, and another group votes to verify. Only when enough votes are reached will the issue be posted to the PR.
Comments concerning only code style, diagnostic hints, or code cleanup will not be posted to the PR and are filtered out directly.
When this review system first launched in March, the proportion of internal PRs receiving substantive review comments rose from 16% to 54%.
The third gate is security review.
Within the team, as long as findings left by code review or security review remain unresolved, the PR cannot be merged: either fix them or close them with a written justification.
The fourth gate is continuous integration (CI) checks, including code standards, type checking, platform tests, and build packaging.
A single ordinary command-line tool (CLI) change may have to run dozens of checks before it is handed over for human review.
Recurring problems must also become the basis for the next round of checks.
CLAUDE.md records project conventions, and REVIEW.md tells the reviewer what to focus on and what can be skipped, so that problems found this time become experience for the next review.
When the same comment is mentioned for the third time, it should be written into the rules.
The fifth gate is human approval, which is the most critical; we will discuss it in detail in the next section.
The sixth gate is merge and release.
After a change passes the previous gates, it still has to enter the merge queue and wait its turn.
When its turn comes, the system places it on the latest version of the main branch, and all checks run again.
This step guards against "each part is fine on its own, but problems arise when combined."
After merging, new features are also not immediately pushed to all users.
They are first hidden behind feature flags and opened only to Anthropic's internal employees. Employees use them intensively every day and often encounter problems earlier than external users.
And the feature flag is like a master switch: without changing code or re-releasing a version, it can decide whether a feature is on or off.
Finally, there is the fallback.
If a problem occurs, pull the master switch first.
The team rotates on-call duty every week, and every incident postmortem must ask: at which gate should this have been stopped?
So, review hasn't disappeared—it has become layer upon layer of checks running through development, merging, and release.
Where are the boundaries of zero-human approval
After the first four gates are all green, the fifth gate decides, based on risk tiering, how many people need to approve this change.
Docs, copy, features visible only internally, and new changes hidden behind flags are low risk; once automated review and security checks pass, they can skip human approval.
Ordinary product changes, as well as sensitive areas like caching, the auto-updater, and system prompts, need one person.
The highest-risk code, plus a handful of designated paths, needs two people.
On the face of it, low-risk changes are already "driverless"?
It's not that simple.
The risk tier is determined by the change itself: the first classifier reads the code and sets the risk, and the second then decides whether additional human approval is needed.
Sensitive paths marked by code owners, as well as all CI workflow files, must be reviewed by a human.
The lightweight approval channel also has a threshold: it is open only to people on the repository's "trusted authors" list; anyone outside the list must find another person to approve.
The person directing the AI to write code counts as a reviewer themselves, and must take responsibility for the change just as if they had written the code by hand.
Zero-human approval does not mean no one is accountable.
Humans must decide whether a feature should be built, whether the architecture is reasonable, and whether the existing checks can cover the risk of this change.
So the Claude Code team has a rule: the code you merge in—if something goes wrong, you usually fix it.
Before clicking approve, the reviewer must be able to explain clearly: what these checks verified, and which risks remain uncovered.
If you can't explain it, don't rush to click approve—first add the necessary review.
AI review can also fail
Automated review can also get itself stuck.
A PR for a CLI project went through more than fifty rounds of review and fixes overnight, until the author finally called a halt manually.
A human can ignore a minor issue in a second, but AI won't—it will dutifully go fix it, and after fixing it there's another commit, and another round of review.
The team used git blame to trace back and found that of the issues the reviewer repeatedly flagged, about 59% were old code that existed before the first round of review. It rarely found new bugs; each round it just dug up a few more old ones.
Later they changed four rules:
If it still hasn't passed after three rounds, remind the author to step back and rethink the approach;
After the first few rounds, review only newly added changes;
Point out issues of the same kind all at once;
Don't repeat issues that have already been raised.
The effect was immediate.
The share of internal PRs that passed after one round of review and fixes rose from 65% to 78%; those needing five or more rounds fell from 8.9% to 1.5%; the average number of reviews dropped from 2.08 to 1.32.

After adjusting the re-review rules, the pass rate after one round of review and fixes rose from 65% to 78%, and the average number of reviews dropped from 2.08 to 1.32.
The skill of review is half about finding problems and half about knowing when to stop.
Does multi-layered review mean it's foolproof?
Anthropic itself gave a counterexample.
On March 26, Claude Code shipped an optimization: when a session sits idle for more than an hour, clean up old reasoning records once.
But a bug made it run the cleanup on every turn after a conversation was resumed. As a result, Claude became forgetful, started repeating itself, and used tools abnormally. The bug wasn't fixed until April 10.

After idling, old reasoning should have been cleaned up only once, but in fact it kept cleaning every turn; the red box marks the mistakenly deleted content.
The official postmortem on April 23 admitted:
This change passed through multiple rounds of human and automated review; unit tests, end-to-end tests, and internal dogfooding all failed to catch it, and just confirming the root cause took more than a week.
The turning point came in the postmortem.
The team re-reviewed the PR that caused the incident with Code Review; when given sufficient context from the relevant repositories, Opus 4.7 found the bug, while Opus 4.6 did not.
This backtest showed that both model capability and context completeness affect detection results. So they enabled review to pull in more repositories.
Today, every incident becomes an exam question.
The team collects PRs, has engineers familiar with the code confirm the bugs in them one by one, and compiles them into a test set.
The reviewer runs against this test set every day. Every time prompts, tools, or models are adjusted, it is also used to check the effect: if the score doesn't improve, the adjustment is not adopted.
The team also didn't overstate things.
After changes go live, developers and on-call staff still need to spot anomalies using data dashboards.
The "circuit breaker" mechanism that automatically tightens approvals based on metrics such as rollback rate has not yet been built. Engineers want to add this safeguard first before letting more changes go through zero-human approval.
Review will inevitably miss things; detection and remediation must keep up too.
One Claude Code team member explained it this way: slowing down does reduce errors, but mainly because you're doing less of everything. So they'd rather spend effort on finding problems faster and fixing them faster.
When one person writes code with AI, what needs to be accepted
AI review only gives opinions; you're still the one who makes the call.
So, don't rush to pursue "not needing to look"—instead, first make AI answer three questions with every delivery.
First, how was it verified?
What checks were run, what were the results, and which cases are not yet covered.
Boris Cherny, the creator of Claude Code, has said that giving Claude a way to verify itself may be the most important thing. He estimates this can make the quality of the final result reach 2 to 3 times the original.

Boris Cherny recommends letting Claude verify its own work to form a feedback loop; he estimates the quality of the final result can be improved to 2–3 times.
Second, what will it affect?
Which users, data, and permissions are involved in the change.
If you have AI add a sharing feature to a reporting tool, you have to ask clearly: who can open the link, and what can be seen after opening it.
Third, how do you roll back if something goes wrong? Can you turn off the new feature with one click and revert to the previous version.
Commit an archive before starting, and keep each change as small as possible. First be able to roll back, then talk about reviewing less.
In addition to these three questions, cultivate three more habits.
First, review with a different "brain."
In the session where code is written, it is easiest to turn a blind eye to one's own bugs.
Open a new session, or have a sub-agent review with a completely fresh context; the local /code-review and /security-review commands can also be run directly.
Second, classify changes into tiers.
For copy changes and style adjustments, merge after checks pass and the actual effect is confirmed; for anything involving login, payment, or data deletion, a human must carefully inspect the key logic and add targeted tests.
Be stricter at first, and once the verification and rollback processes run smoothly, gradually reduce manual review of low-risk changes.
Third, if three rounds don't get it through, change your approach.
If AI has revised for three rounds and is still going in circles, don't push it for a fourth round—first ask whether the approach itself is wrong.
The most important point: AI saying "passed" does not mean you have completed acceptance.
You had it write the code, and you must also be responsible for the results after it goes live.
The goal of the Claude Code team is to have most PRs involve at most one person, while keeping the rollback rate and incident rate in check.
Human attention should be placed more on judging risks, confirming whether checks are sufficient, and how to remedy things after errors occur.
People don't have to read every line of code, but every release must have someone responsible for it.
References:
https://claude.dev/blog/solving-code-review-at-anthropic/?utm_source=chatgpt.com
https://www.anthropic.com/research/april-23-postmortem?utm_source=chatgpt.com
https://x.com/bcherny/status/2007179861115511237
Editor: Yuanyu
This article comes from the WeChat public account "Xinzhiyuan" (ID: AI_era), author: ASI Revelation